8 Databricks Competitors and Alternatives for 2026 (With Prices)
Eight Databricks alternatives sorted by the job you use Databricks for, with prices from each vendor's own page.

Updated · 10 min read
The short answer
The best Databricks alternatives are Snowflake, BigQuery or Redshift for SQL analytics, Microsoft Fabric for one platform with Power BI, Dremio or ClickHouse for specialist jobs, Amazon EMR for Spark on its own, and Mammoth for recurring reports.
Table of contents
- The 8 Databricks alternatives at a glance
- Which Databricks alternative fits your job?
- 1. Mammoth: best for recurring business reports
- 2. Snowflake: best for SQL analytics and BI
- 3. Google BigQuery: best for serverless SQL on Google Cloud
- 4. Amazon Redshift: best for a data warehouse on AWS
- 5. Microsoft Fabric: best for one platform with Power BI
- 6. Dremio: best for querying the files in your data lake
- 7. ClickHouse: best for fast dashboards on event data
- 8. Amazon EMR: best for Spark without the Databricks layer
- Other Databricks competitors
- Which Databricks alternative to choose
- How to move off Databricks
- Frequently Asked Questions
Most teams don't use all of Databricks. One team runs SQL dashboards on it. Another runs a nightly Spark job. A third uses it to rebuild the same sales report every Monday, and wonders why the bill has its own meeting.
So the right alternative depends on which part you use. I sorted the eight main Databricks competitors by job, and read every price off the vendor's own pricing page. I work on Mammoth, which is one of the eight, for the reporting job.
The 8 Databricks alternatives at a glance
| Tool | Best for | Starting price |
|---|---|---|
| Mammoth | Recurring business reports | Free, then $39/month |
| Snowflake | SQL analytics and BI | $2 a credit on demand |
| Google BigQuery | Serverless SQL on Google Cloud | 1 TiB of queries free a month, then $6.25 a TiB |
| Amazon Redshift | A data warehouse on AWS | $0.375 an RPU-hour (Serverless) |
| Microsoft Fabric | One platform with Power BI | $0.18 a capacity unit an hour |
| Dremio | Querying files in your data lake | Free Community Edition, Cloud $0.20 a DCU |
| ClickHouse | Fast dashboards on event data | Open source, Cloud from $0.218 a compute unit-hour |
| Amazon EMR | Spark without the Databricks layer | EMR charge on top of the EC2 server price |
For comparison, Databricks charges $0.07 to $0.95 a DBU on its Premium tier, plus the cloud servers underneath. Our Databricks pricing guide breaks that bill down.
Free options: Mammoth's free plan, BigQuery's free terabyte of queries, Dremio's Community Edition, and open-source ClickHouse or Apache Spark on your own servers.
Each of these does one part of what Databricks does. So the first step is naming your part.
Which Databricks alternative fits your job?
Databricks is a platform for data engineering, SQL analytics and machine learning on the same data. That breadth is why teams buy it. It's also why many of them pay for far more than they use.
- SQL analytics and BISnowflakeBigQueryRedshift
- One platform on MicrosoftMicrosoft Fabric
- Query the files in your lakeDremio
- Fast dashboards on event dataClickHouse
- Spark without the platformAmazon EMRApache Spark
- Recurring business reportsMammoth
If you train models and run Spark across a big data lake every day, Databricks may still be the right tool. If you mostly do one of the jobs above, the tool built for that job is usually simpler and often cheaper.
Here's each one, starting with the job I know best.
1. Mammoth: best for recurring business reports
Best for: teams whose Databricks work is mostly the same reports, rebuilt every week or month.
Mammoth connects to your data, cleans and combines it with saved steps, and builds the dashboard with AI. Every refresh reruns the whole chain, so the Monday report builds itself.
It can sit on top of the warehouse you already have, or replace it for reporting:
- Connect the sources. Databricks, Snowflake, BigQuery and Redshift connect on every paid plan, next to more than 100 apps, databases and files.
- Clean and combine once. Pick steps, or ask in plain words and Mammoth writes the SQL. The steps rerun on every refresh.
- Describe the dashboard, such as "revenue by region against last year". Edit any chart afterwards.
- Set the schedule. The data refreshes weekly, daily or every three hours depending on the plan.
Price: free for files and standard databases. Warehouses and every other connector come with paid plans from $39/month billed annually. Viewers are free on every plan.
Where it stops
- It doesn't train machine learning models or run Spark jobs.
- It isn't a warehouse for very large historical tables. For that, keep Databricks or pick one of the warehouses below.
Build the reports your Databricks jobs feed, without a cluster to manage.
That covers reporting. If your team mostly writes SQL against big tables, a warehouse is the closer match.
2. Snowflake: best for SQL analytics and BI
Best for: analysts and BI teams who live in SQL.
Snowflake is a cloud data warehouse that keeps storage and compute separate. You size a virtual warehouse for the work, and it suspends when nobody is querying. It also shares live data between accounts without copying it.
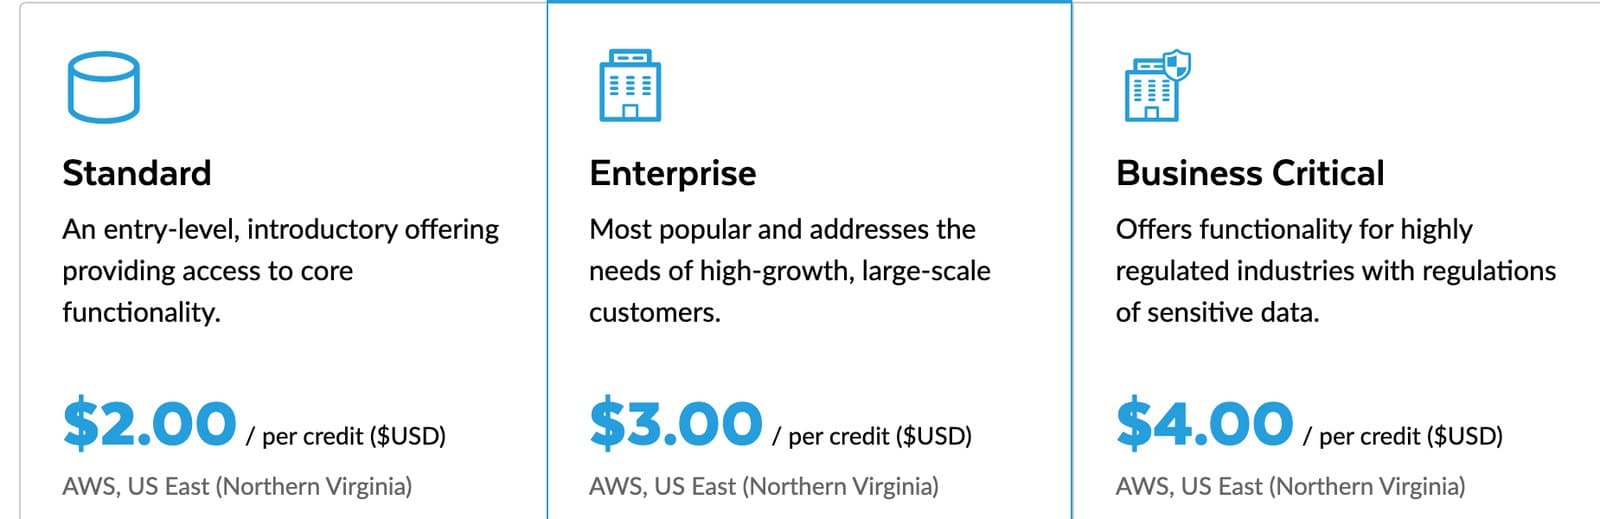
Price: $2 a credit on Standard, $3 on Enterprise and $4 on Business Critical, in the US regions on demand. Storage is $23 per TB a month. Our Snowflake pricing guide has a cost estimator and worked examples.
Where it stops
- A warehouse left running bills by the second, so cost control takes some attention.
- It's SQL first. Teams whose main work is Spark and notebooks usually stay on Databricks.
If you're on Google Cloud, BigQuery does the same job without warehouses to size at all.
3. Google BigQuery: best for serverless SQL on Google Cloud
Best for: teams on Google Cloud who don't want to manage compute.
BigQuery is serverless. There is nothing to start or stop. By default you pay for the data each query scans, and the first terabyte each month is free.
Price: the first 1 TiB of queries a month is free, then $6.25 per TiB scanned on demand. The first 10 GiB of storage is free, then active storage costs about $0.02 per GiB a month. Teams with steady workloads can pay per slot-hour instead.
Where it stops
- A query that scans a whole large table costs the whole table, so careless queries add up.
- It works best inside Google Cloud.
AWS has its own answer to the same job.
4. Amazon Redshift: best for a data warehouse on AWS
Best for: teams whose data already lives in AWS.
Redshift is AWS's data warehouse. Redshift Serverless sizes compute for you and bills only while queries run. Provisioned clusters suit steady, predictable loads.
Price: Serverless costs $0.375 per RPU-hour in US East, with base capacity from 4 RPUs. Provisioned clusters start at $0.543 an hour. New Serverless users can get a $300 credit for 90 days.
Where it stops
- It makes the most sense if you're already on AWS.
- Provisioned clusters reward tuning, which takes engineering time.
If your company runs on Microsoft instead, Fabric bundles the warehouse with the reporting tool.
5. Microsoft Fabric: best for one platform with Power BI
Best for: companies on Microsoft 365 and Azure that already use Power BI.
Fabric puts a lakehouse, a warehouse, data pipelines and Power BI in one service with one capacity bill. It's the closest thing on this list to Databricks' all-in-one approach.
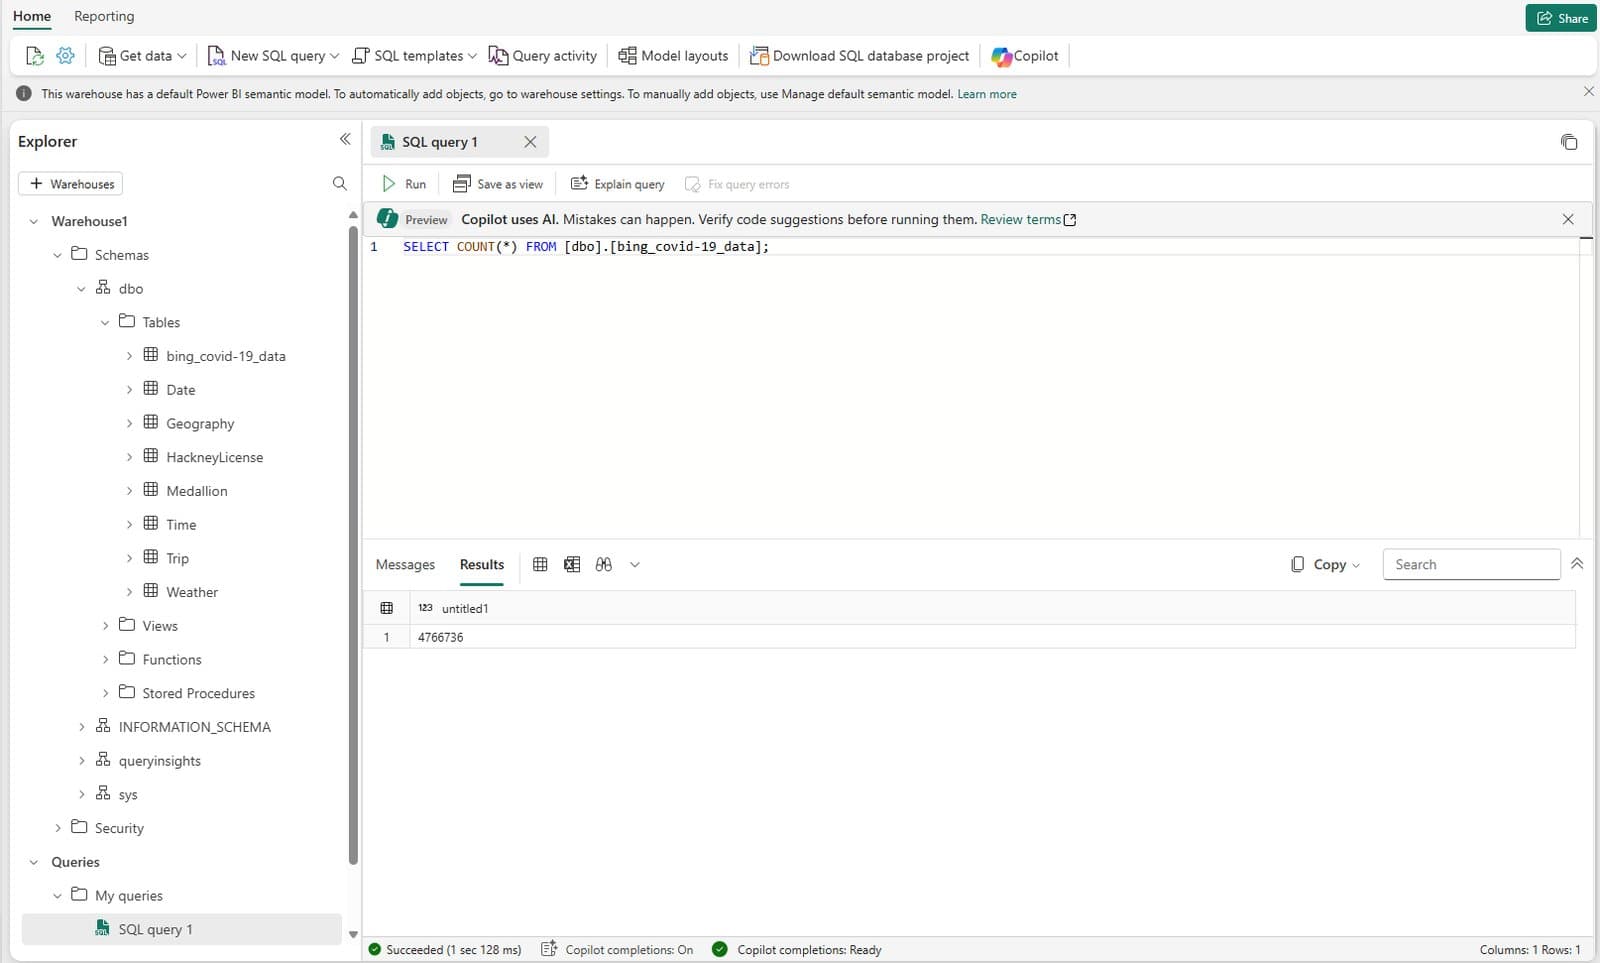
Price: $0.18 per capacity unit an hour on pay-as-you-go in Azure East US. The smallest capacity, F2, has 2 units, which is $262.80 a month if it runs all month. Hot storage in OneLake costs $0.026 per GB a month.
Where it stops
- Capacity pricing takes some learning, since every workload draws on the same pool of units.
- It ties you closely to Microsoft.
If you'd rather keep your data in open files and avoid any one vendor's format, Dremio takes the opposite approach.
6. Dremio: best for querying the files in your data lake
Best for: teams who want lakehouse queries on open file formats.
Dremio queries data where it already sits in your lake, using open table formats such as Apache Iceberg, so you don't copy it into a warehouse first. Its Enterprise edition also runs on your own servers.
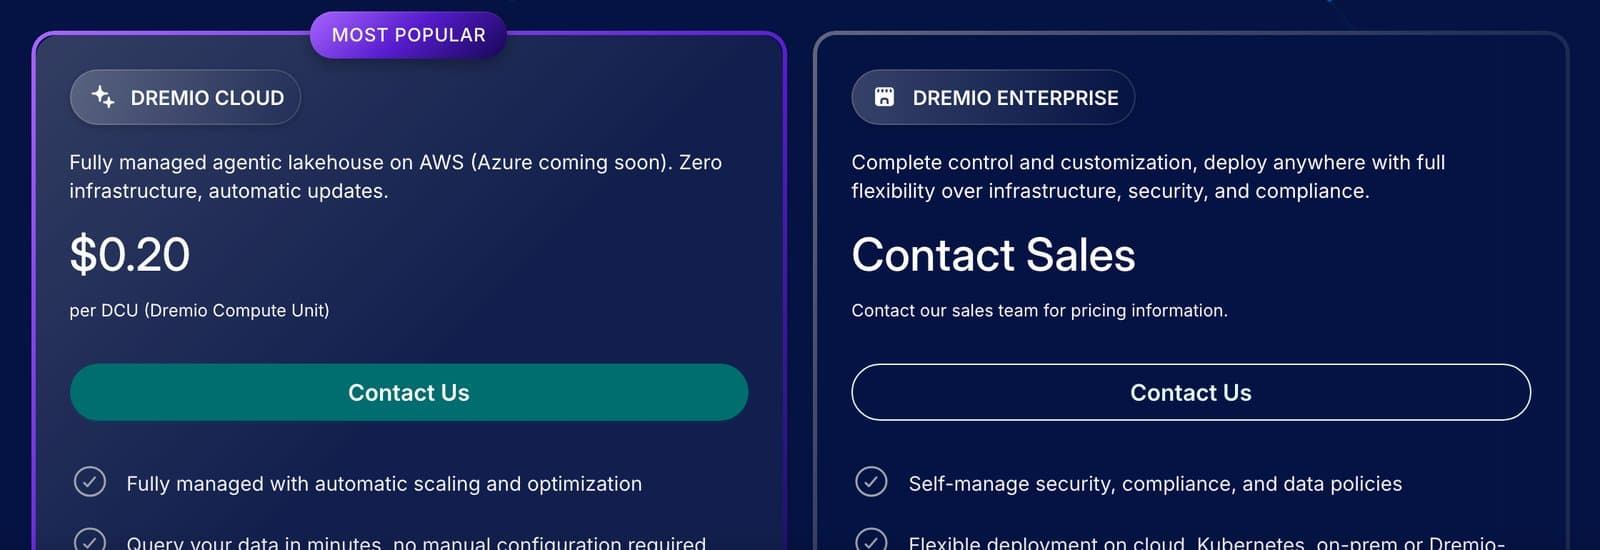
Price: Community Edition is a free query engine for your own machines. Dremio Cloud costs $0.20 per DCU, billed on engine size and running time, with a $400 credit for 30 days. Enterprise is quoted.
Where it stops
- Its ecosystem is smaller than Databricks'.
- It's a query engine, not a notebook environment for data science.
Dremio is about flexibility. ClickHouse is about speed.
7. ClickHouse: best for fast dashboards on event data
Best for: product and engineering teams with huge streams of events.
ClickHouse is an open-source column database built for fast analytical queries over very large tables. Teams use it for live dashboards, logs and product analytics.
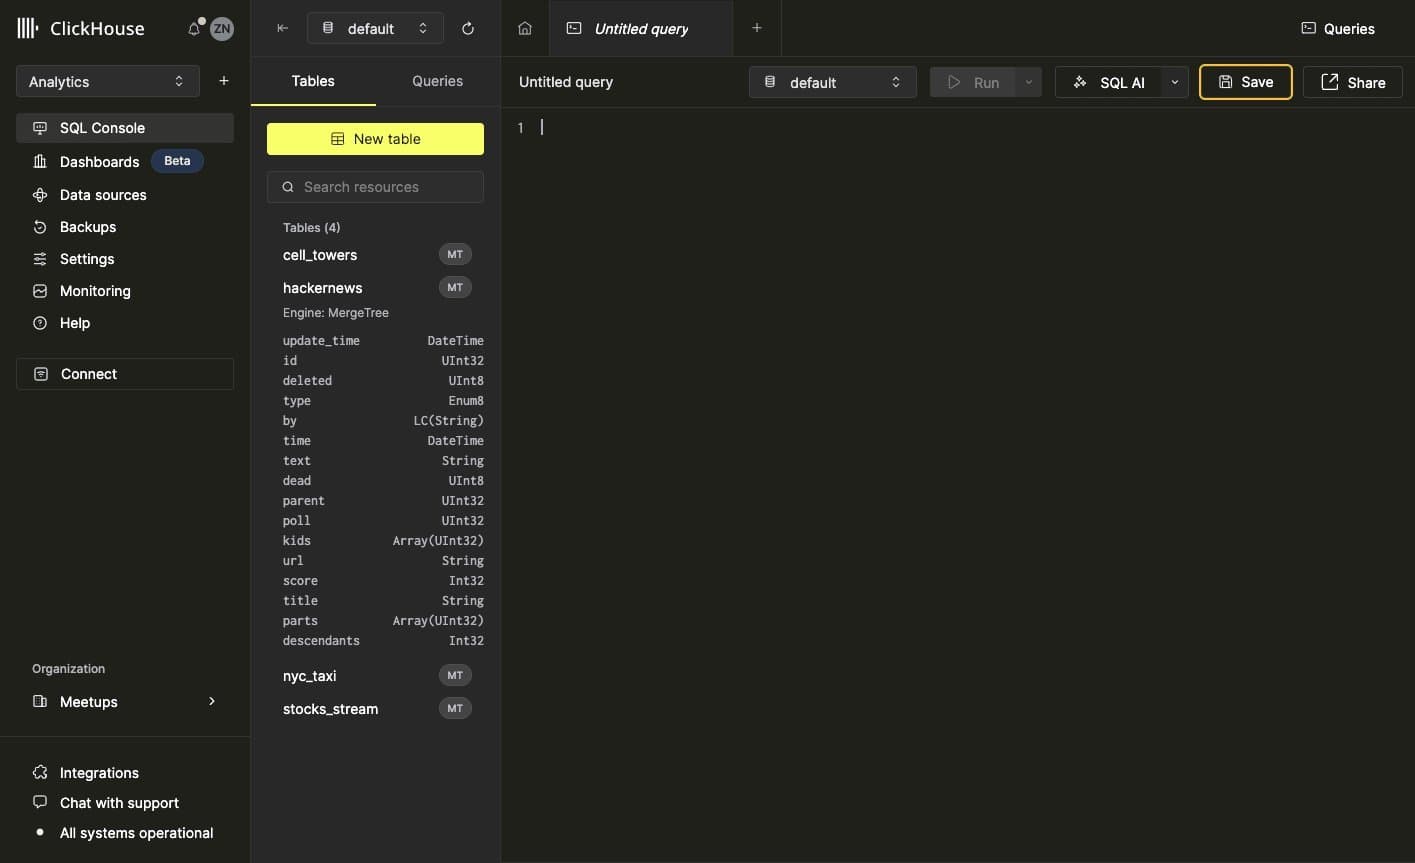
Price: free and open source if you host it. ClickHouse Cloud is usage-based with no monthly minimum, from $0.21811 per compute unit-hour on the Basic tier in AWS us-east-1, plus $25.30 per TB of storage a month. New accounts get $300 of credit for 30 days.
Where it stops
- It's a fast database, not an all-in-one platform.
- Joins across many large tables need more care than in a general warehouse.
The last option keeps Spark and drops the platform around it.
8. Amazon EMR: best for Spark without the Databricks layer
Best for: engineers who want Spark and are happy to run it themselves.
EMR runs Apache Spark, Hive and other open-source engines on AWS servers. You get the same Spark engine Databricks was built on, without Databricks' notebooks, tuning and per-DBU charge. If you want no vendor at all, Apache Spark itself is free to run on your own servers.
- EC2 serverThe machine itself, c4.2xlarge$0.398
- EMR chargeAdded by AWS for running EMR$0.105
- One node, one hour$0.503
Price: EMR adds its own charge on top of the EC2 server price, billed per second with a one-minute minimum. AWS's own example is a c4.2xlarge server at $0.398 an hour with $0.105 an hour for EMR in US East. Spot servers can cost up to 90% less than on demand.
Where it stops
- You lose Databricks' collaborative notebooks and automatic tuning.
- Someone on your team has to own the clusters.
Those are the eight I'd look at first. A few more names come up in almost every Databricks comparison, so here's where they fit.
Other Databricks competitors
Palantir Foundry. An operating platform built around Palantir's Ontology, which connects data to the decisions and workflows that run on it. It competes with Databricks in large enterprises and government, at enterprise contract prices.
Cloudera. A data platform that runs in your own data centres, in public clouds and at the edge, with the same services in each. It's a common choice when data can't leave your own servers.
Teradata. An enterprise analytics platform that runs on AWS, Azure and Google Cloud, or on premises and hybrid. It suits very large companies with existing Teradata estates.
Starburst. A query layer built around Trino and Apache Iceberg that queries data where it already sits, without moving it. It runs in the cloud, on premises or hybrid.
Google Dataproc. Google Cloud's managed Apache Spark service, now called Managed Service for Apache Spark, with serverless Spark or managed clusters. It's the Google Cloud equivalent of Amazon EMR.
Alteryx. Data preparation and analytics for analysts, now sold as Alteryx One. Starter Edition costs $250 a user a month billed annually, and the larger editions are quoted. Our Alteryx alternatives guide compares it with similar tools.
The quickest way to pick from all of these is to start from your job.
Which Databricks alternative to choose
- If
You rebuild the same reports every week or month.
- If
Your analysts work in SQL and BI tools.
Use Snowflake
- If
You're on Google Cloud and want nothing to manage.
Use Google BigQuery
- If
Your data already lives in AWS.
Use Amazon Redshift
- If
You run on Microsoft and use Power BI.
Use Microsoft Fabric
- If
You want to query open files in your lake.
Use Dremio
- If
You need fast dashboards on event data.
Use ClickHouse
- If
You want Spark and can run it yourselves.
Use Amazon EMR
How to move off Databricks
- List what runs on it. Write down every job, dashboard and notebook, and who owns each.
- Sort them by job, using the map above. Most lists split into two or three groups.
- Move one group first, usually reporting, since it's the easiest to check.
- Run both side by side for a month and compare the numbers and the bill.
- Switch off what moved, then decide whether what's left still needs Databricks.
Frequently Asked Questions
Who are Databricks' biggest competitors?
Snowflake is the most direct competitor, followed by Microsoft Fabric, Google BigQuery and Amazon Redshift. For specific jobs, Dremio competes on lakehouse queries, ClickHouse on real-time analytics and Amazon EMR on managed Spark.
Are Snowflake and Databricks competitors?
Yes. Both sell a cloud platform for analytics. Snowflake started as a SQL warehouse and Databricks as a Spark platform, and each has added what the other does.
Is Palantir a Databricks competitor?
In part. Palantir Foundry competes for the same large enterprise and government data projects, but it's built around running operations and decisions on the data rather than around Spark and SQL analytics.
What is the cheapest alternative to Databricks?
For Spark, Apache Spark on your own servers has no licence fee, and Amazon EMR adds a small charge to the server price. For SQL, BigQuery's first terabyte of queries each month is free. For reports, Mammoth has a free plan, with paid plans from $39/month.
Is there an open-source alternative to Databricks?
Yes. Apache Spark, the engine Databricks is built on, is open source. ClickHouse is open source, and Dremio has a free Community Edition.
Is there an on-premises alternative to Databricks?
Yes. Cloudera, Teradata, Starburst and Dremio Enterprise all run on your own servers, and ClickHouse and Apache Spark can be self-hosted anywhere. Databricks itself runs in the public cloud.
Can I replace Databricks for reporting only?
Yes. If Databricks mostly feeds recurring reports, a reporting tool such as Mammoth can connect to the same data, or to the original sources, and rebuild the reports on a schedule.


