Best Data Transformation Tools for 2026 (Free and Paid)
Seven data transformation tools compared by who builds the transformations, with prices from each vendor's own page.

· 8 min read
The short answer
The best data transformation tools are Mammoth for analysts, dbt or SQLMesh for SQL teams, Coalesce for a visual canvas that writes SQL, and Matillion, AWS Glue or Azure Data Factory for engineers on a cloud platform.
Table of contents
- The best data transformation tools at a glance
- What data transformation tools do
- 1. Mammoth: best for analysts and business teams
- 2. dbt: best for SQL models in a warehouse
- 3. SQLMesh: best for open-source SQL transformation
- 4. Coalesce: best for a visual canvas that writes SQL
- 5. Matillion: best for visual pipelines on cloud platforms
- 6. AWS Glue: best for Spark jobs on AWS
- 7. Azure Data Factory: best for visual data flows on Azure
- Other data transformation tools
- Which data transformation tool to choose
- How to choose a data transformation tool
- Frequently Asked Questions
Raw data rarely arrives in the shape a report needs. Dates come in three formats, customer IDs don't match between systems, and the sales table has one row per line item when finance wants one row per order.
Data transformation tools fix that once and repeat the fix every time new data lands. I compared the main ones by who builds the transformations, from analysts to data engineers, and read every price off the vendor's own page. I work on Mammoth, which is one of them, so I'll say where it fits and where it doesn't.
The best data transformation tools at a glance
| Tool | Best for | Starting price |
|---|---|---|
| Mammoth | Analysts and business teams | Free, then $39/month |
| dbt | SQL models in a warehouse | Free Developer seat, Starter $100 a user a month |
| SQLMesh | Open-source SQL transformation | Free, Apache 2.0 |
| Coalesce | A visual canvas that writes SQL | Free Developer plan, Starter $150 a user a month |
| Matillion | Visual pipelines on cloud platforms | Quote, credit packages |
| AWS Glue | Spark jobs on AWS | $0.44 a DPU-hour |
| Azure Data Factory | Visual data flows on Azure | $0.273 a vCore-hour for data flows |
Free options: Mammoth's free plan, dbt's free Developer seat, SQLMesh, Coalesce's Developer plan, and Google Dataform, which costs nothing beyond the BigQuery queries it runs.
Before the tools, it helps to see where transformation happens.
What data transformation tools do
A data transformation tool turns raw data into the shape you need. That means cleaning values, joining tables, changing types, aggregating rows and calculating new columns, and then repeating those steps on every new batch of data.
The main split is where the transformation runs. In ETL, the data is transformed before it lands in the warehouse. In ELT, the raw data is loaded first and transformed inside the warehouse, which is how most modern tools work.
Transform first, then load the clean result.
Load the raw data, then transform it inside the warehouse.
The second split is who writes the transformations. That decides the tool more than any feature list.
- Steps and AI for the people who own the reportsAnalysts and business teamsMammoth
- SQL models inside your warehouseAnalytics engineersdbtSQLMeshCoalesce
- Visual pipelines on a cloud platformData engineersMatillionAWS GlueAzure Data Factory
I'll start with the analyst row, since it's the one I know best.
1. Mammoth: best for analysts and business teams
Best for: analysts and finance or operations teams who transform the same data every week or month.
Mammoth builds a transformation as a pipeline of steps, such as filter, join, replace values or calculate a column. You can pick each step from a menu, describe it in plain words, or write SQL. The steps rerun in order every time the data refreshes.
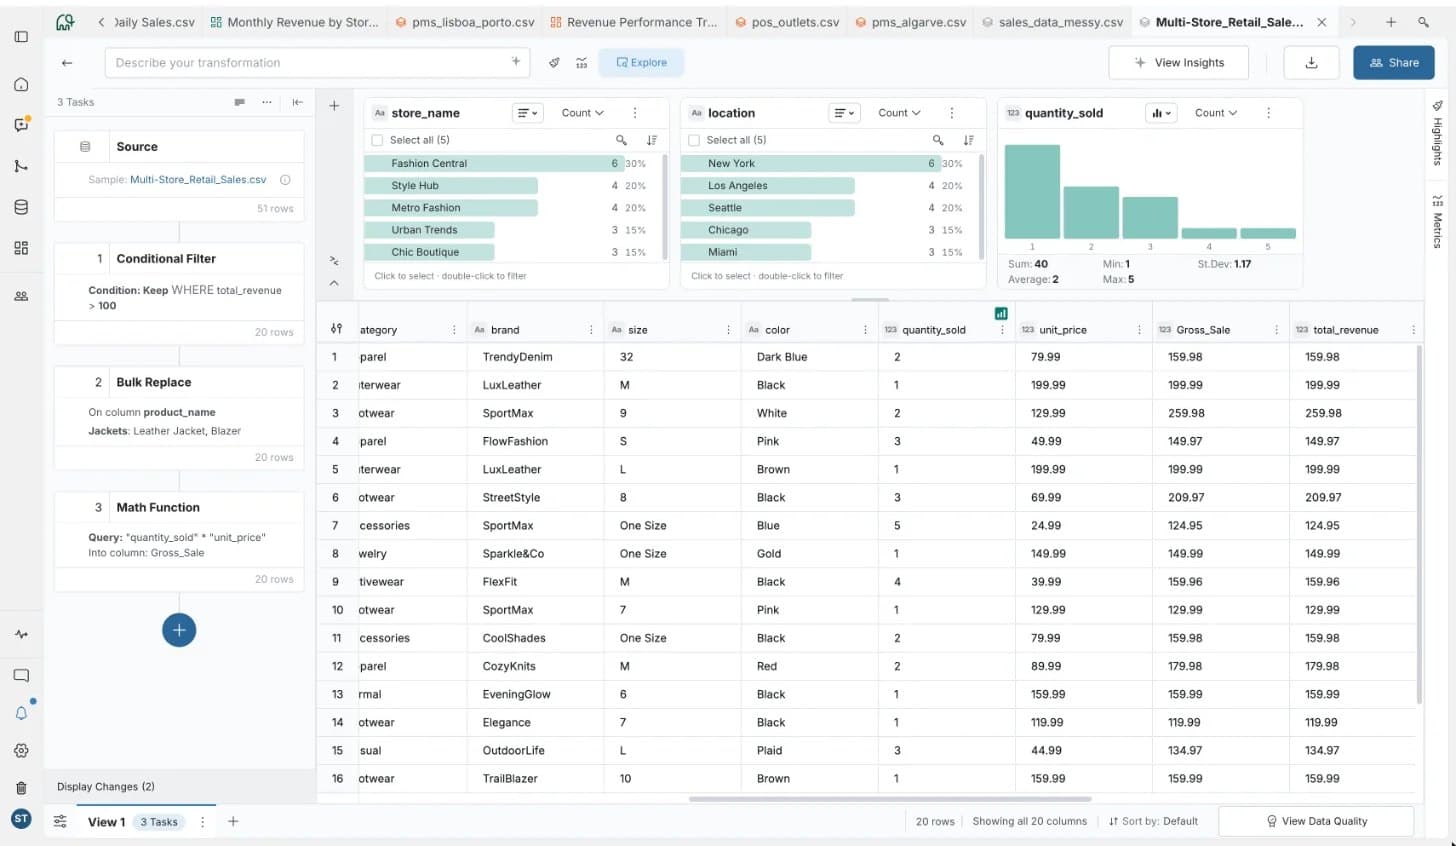
Setting up a transformation takes four steps:
- Connect the data, from files, databases, warehouses such as Snowflake and BigQuery, or more than 100 apps.
- Add the steps, by picking them or typing what you want, such as "keep orders over $100 and add a gross sale column". Mammoth shows each AI step before it runs.
- Check the result in the grid, then fix any step without starting again.
- Schedule it, and send the output to a dashboard, a file, or a database such as PostgreSQL, BigQuery or Redshift.
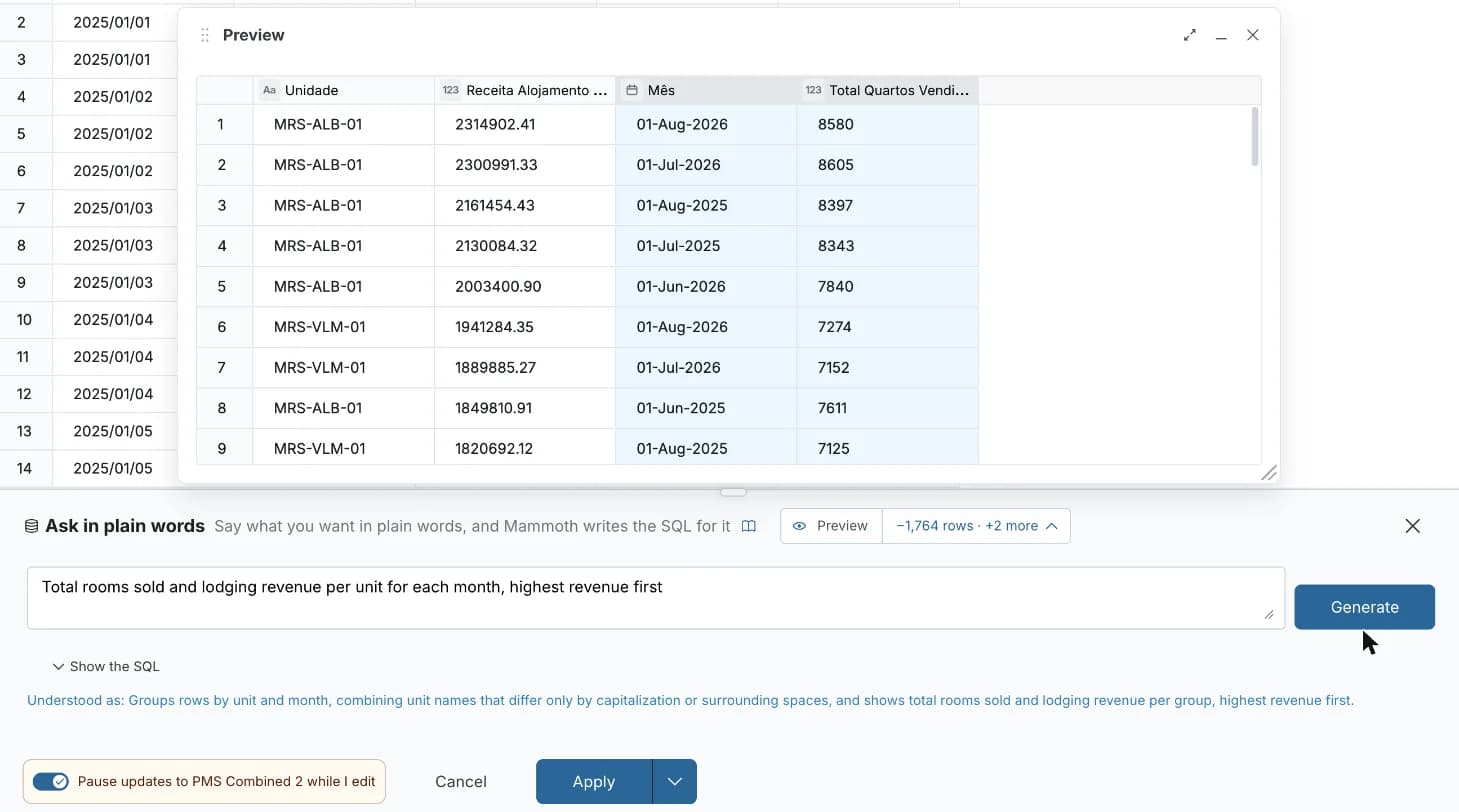
Price: free for files and standard databases. Warehouses, apps and writing results to a database come with paid plans from $39/month billed annually. Viewers are free on every plan.
Where it stops
- It isn't built for engineers who want every transformation in Git with code review.
- For very large warehouse tables, a tool that runs inside the warehouse, such as dbt, is the better fit.
Build the transformation once, then let it rerun on every refresh.
If your team writes SQL and the data already sits in a warehouse, the next three tools are the usual choice.
2. dbt: best for SQL models in a warehouse
Best for: analytics engineers who write SQL and work in Git.
dbt turns SQL select statements into tables and views inside your warehouse. You write each transformation as a model, dbt works out the order to run them in, and tests check the results. The dbt platform adds a browser IDE and scheduling.
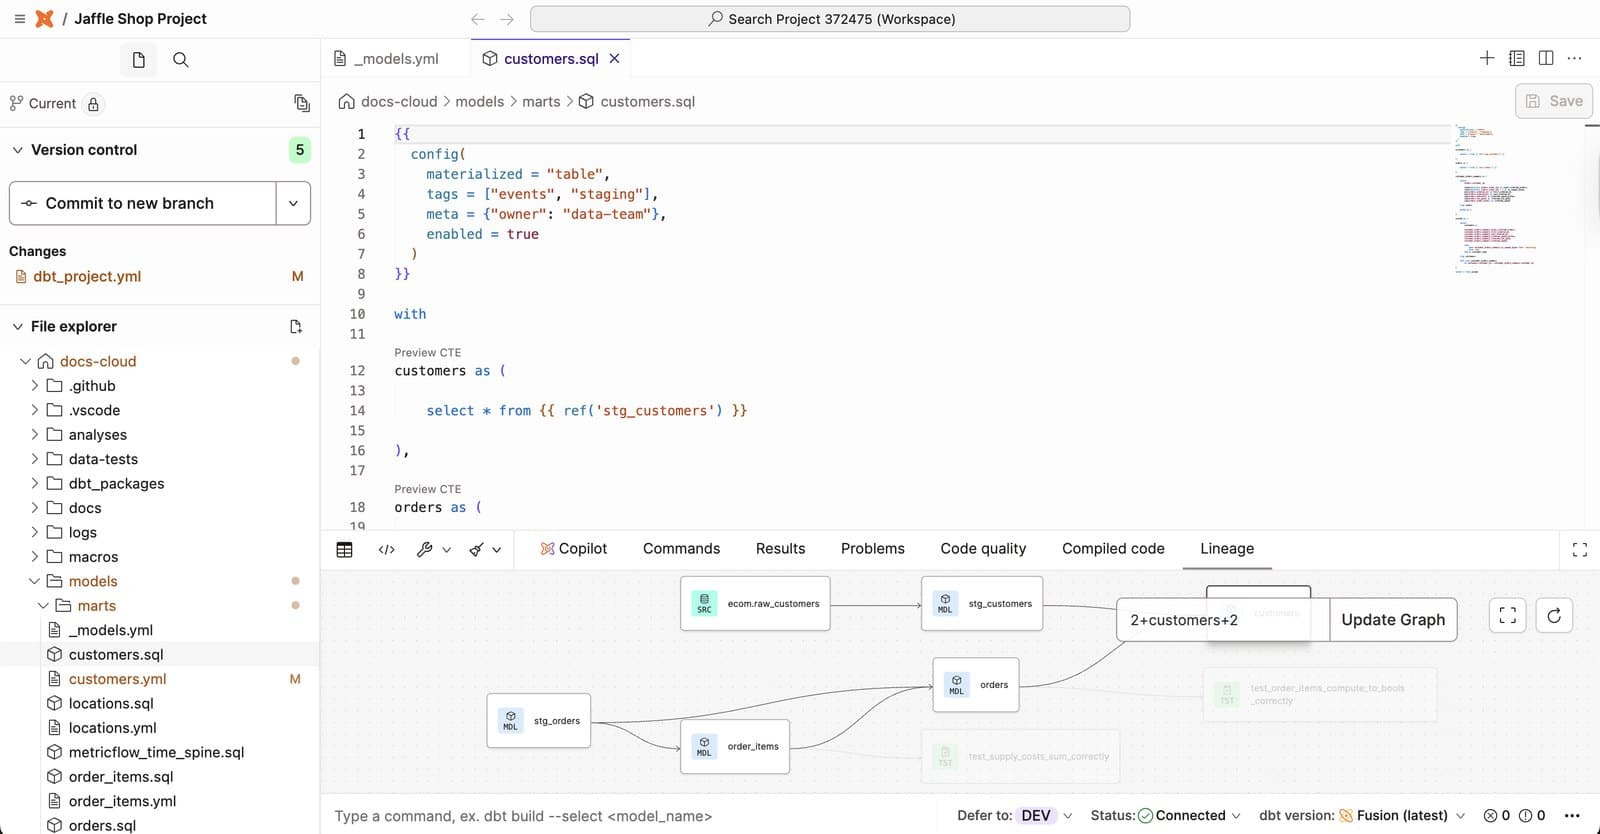
Price: the Developer plan is free for one seat. Starter costs $100 a user a month for up to five developer seats, and Enterprise is quoted. Our dbt pricing guide covers the rest.
Where it stops
- Everything is SQL, so analysts who don't write it can't change the models.
- It only transforms data that is already in a warehouse.
SQLMesh does the same job and is free to run yourself.
3. SQLMesh: best for open-source SQL transformation
Best for: teams who want dbt-style SQL models without a paid platform.
SQLMesh is an open-source data transformation framework under the Apache 2.0 licence. It shows what a change will do before you apply it, and it can run only the new data in incremental models.
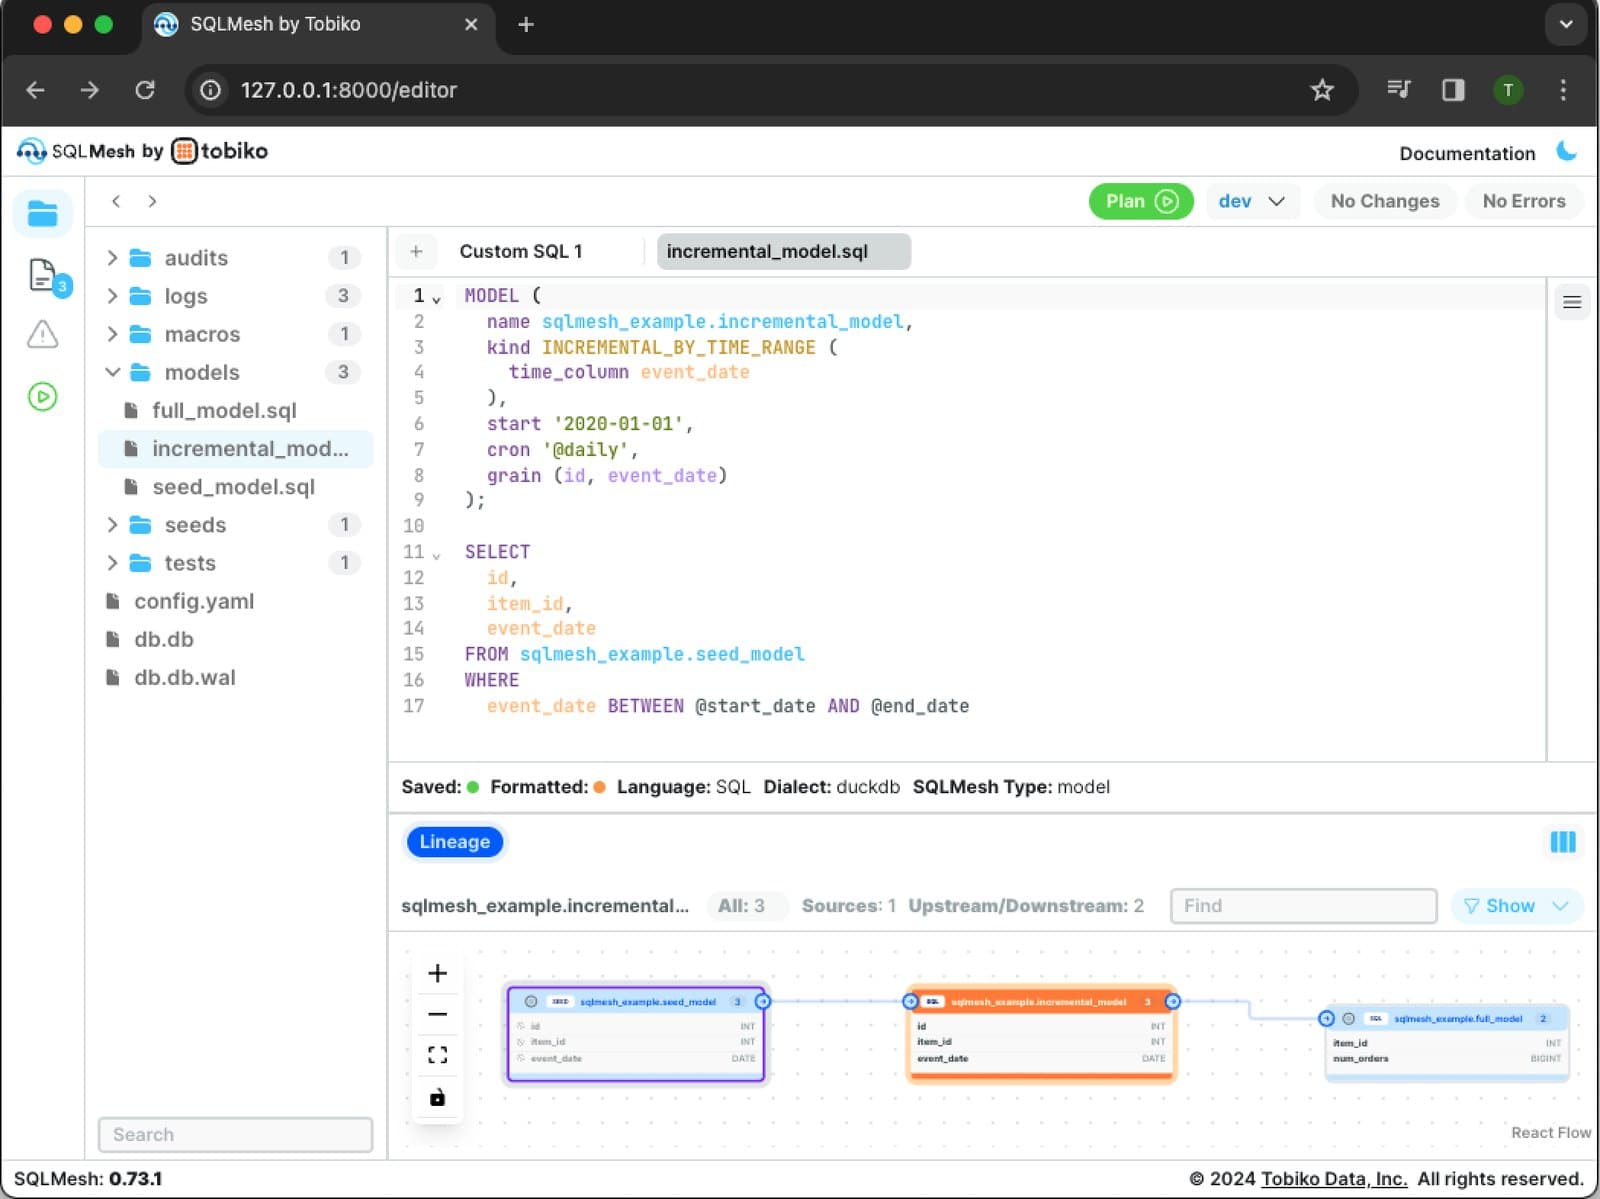
Price: free.
Where it stops
- You host and run it yourself.
- Its community is smaller than dbt's.
Coalesce keeps the SQL but adds a visual canvas on top.
4. Coalesce: best for a visual canvas that writes SQL
Best for: data teams who want SQL standards without writing every line by hand.
Coalesce lets you build transformations as nodes on a visual canvas, and it generates the SQL that runs in your warehouse. Its plans also include data quality checks and a catalog.
Price: the Developer plan is free for one user and 2,000 actions a month. Starter costs $150 a user a month billed annually, for up to four users, and Enterprise is quoted.
Where it stops
- It still assumes the data is in a warehouse.
- Analysts outside the data team won't build in it alone.
The next three tools build pipelines visually and run them on a cloud platform.
5. Matillion: best for visual pipelines on cloud platforms
Best for: data engineers who want low-code pipelines that run on Snowflake and other cloud data platforms.
Matillion's Data Productivity Cloud builds pipelines on a visual canvas, with SQL or Python where you need it. Its AI, Maia, can build and manage pipelines from a description.
Price: quoted. Matillion uses credits, consumed by pipeline task hours and by extra developer users, and its Teams and Scale plans come as annual packages. You can buy directly or through AWS, Azure or Snowflake.
Where it stops
- Prices aren't published, so you need a sales call to budget.
- It's built for data engineers, not report owners.
If your company runs on AWS, Glue is the native option.
6. AWS Glue: best for Spark jobs on AWS
Best for: engineering teams whose data lives in AWS.
AWS Glue runs transformation jobs on Apache Spark without servers to manage. You can author a job in a visual editor, a notebook or a script.
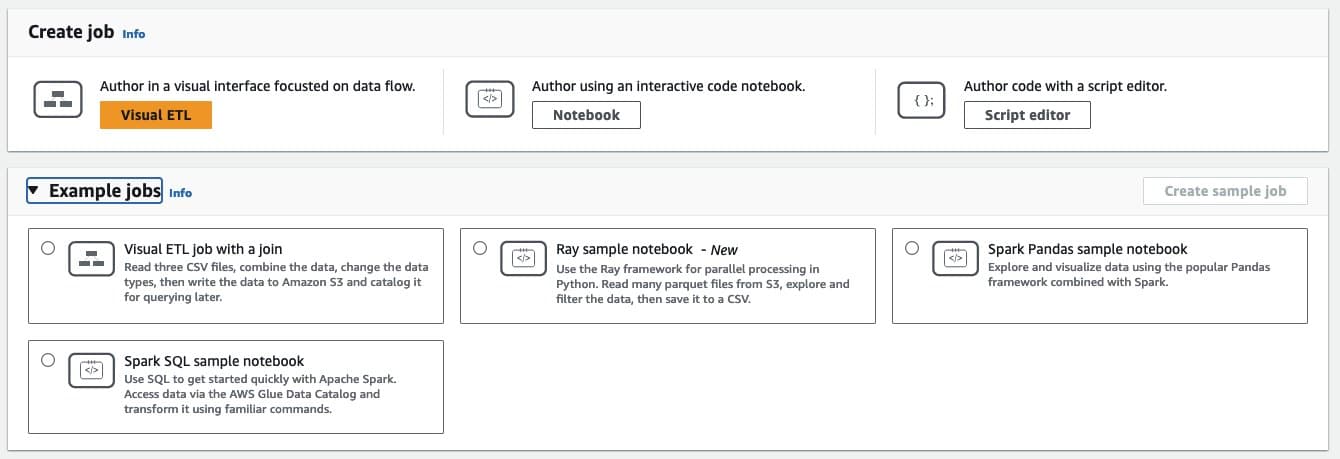
Price: $0.44 per DPU-hour for ETL jobs, billed by the second. Prices can vary by region.
Where it stops
- It makes most sense if you're already on AWS.
- Spark jobs need engineers to write and tune them.
Azure has a visual equivalent.
7. Azure Data Factory: best for visual data flows on Azure
Best for: teams on Microsoft Azure who want visual transformations.
Azure Data Factory moves and transforms data across Azure. Its mapping data flows let you design transformations visually, preview the result, and run them on managed Spark clusters.
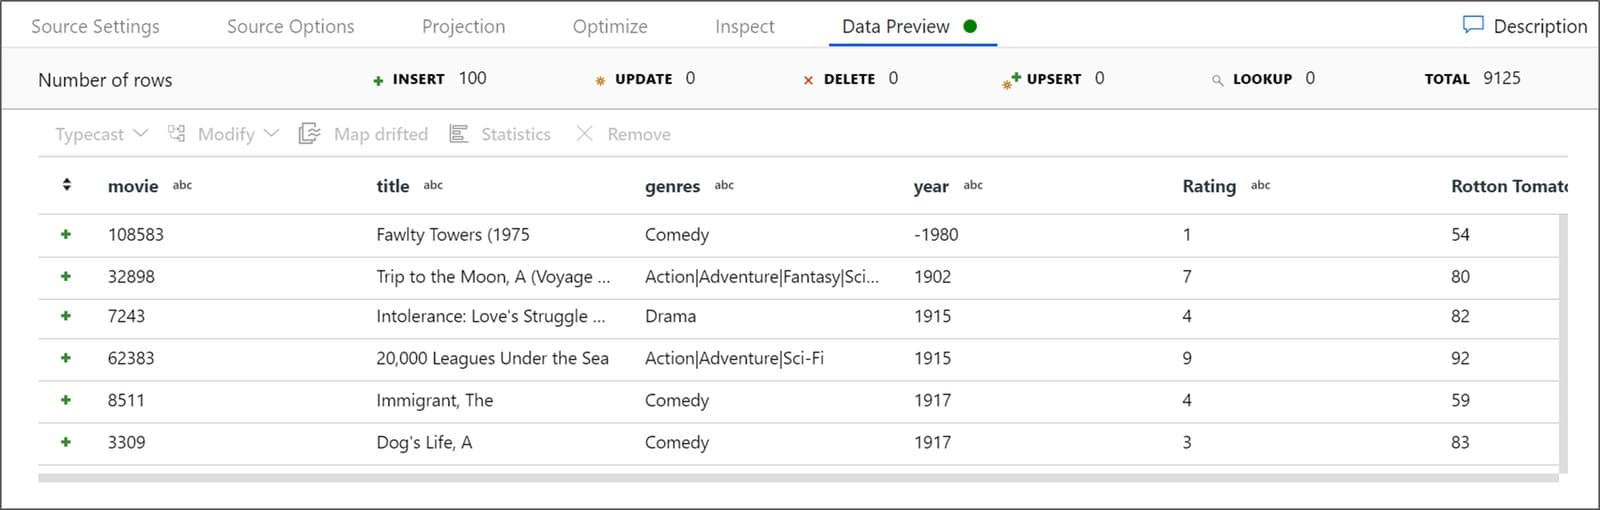
Price: data flows cost $0.27325 per vCore-hour on General Purpose compute in East US, and pipeline activity runs cost $1 per 1,000.
Where it stops
- It's tied to Azure.
- Costs grow with cluster size and running time, so they take watching.
Those are the seven I'd look at first. A few more names come up in most comparisons.
Other data transformation tools
Google Dataform. SQL transformations for BigQuery, managed in Git. Dataform itself is free, and you pay BigQuery for the queries it runs.
Fivetran Transformations. Runs dbt models after each Fivetran sync. The first 5,000 model runs a month are free, then from $0.01 a run.
Alteryx. Visual workflows for analysts. Starter Edition costs $250 a user a month billed annually. Our data preparation tools guide covers it alongside other analyst tools.
Informatica. Enterprise data integration with transformation built in, priced by processing units through sales.
Qlik Talend. Data integration and transformation in Qlik Talend Cloud, quote-only. Our Talend pricing guide explains the editions.
Which data transformation tool to choose
- If
Analysts transform the same data every week or month.
- If
Your team writes SQL and works in Git.
Use dbt
- If
You want SQL models on open source.
Use SQLMesh
- If
You want a visual canvas that writes SQL.
Use Coalesce
- If
Engineers build visual pipelines on a cloud data platform.
Use Matillion
- If
Your data lives in AWS.
Use AWS Glue
- If
Your data lives in Azure.
Use Azure Data Factory
How to choose a data transformation tool
- Name who will build the transformations, an analyst or an engineer. That rules out half the list.
- Check where the data lives, in files and apps or already in a warehouse.
- Pick one transformation you repeat every week, such as cleaning a sales export, and build it in two tools.
- Run it on next week's data and see which one needed fixing.
- Price the year, including the users who will build and the compute it runs on.
Frequently Asked Questions
What are data transformation tools?
Software that turns raw data into the shape you need by cleaning values, joining tables, changing types and calculating new columns, then repeats those steps on every new batch of data.
What is data transformation software?
The same thing. "Software" and "tools" are used interchangeably, from desktop apps such as Alteryx to cloud services such as dbt and AWS Glue.
Is dbt an ETL tool?
Not quite. dbt does the transform step only. It doesn't extract or load data, so teams pair it with a loading tool and run dbt inside the warehouse, which is the ELT pattern.
What are the four types of data transformation?
A common way to group them is cleaning (fixing errors and formats), structuring (joining, splitting and pivoting), enriching (adding calculated or looked-up values) and aggregating (summarising rows into totals).
Are there free data transformation tools?
Yes. SQLMesh is open source, Google Dataform is free apart from BigQuery costs, and Mammoth, dbt and Coalesce have free plans.
Can business users transform data without SQL?
With most tools here, someone needs SQL or code. Mammoth lets analysts pick steps or describe them in plain words, and Alteryx uses visual workflows.


